Nvidia’s H200 and L4 are 2 of the most used and known datacenter GPUs in recent times. Nvidia has a range of GPU variants in terms of architecture like Ada Lovelace, Hopper, Blackwell. And each of these have multiple GPUs like A100, H100, H200, RTX PRO 6000, B200, B300 each serve a different purpose and were built with the specific problem in mind. Amongst all this H200 and L4 have been proven to be the most used and sensible choice for most businesses in multiple use cases. So yes, this blog is going to specifically talk about H200 and L4, nothing else. More specifically, what is the difference between these two. It is very evidently used for completely different use cases. In this blog we are going to answer the question ‘WHY?”
-
Why H200 is known as training GPUs and L4 is not used for training?
-
Why L4 is used for inferencing, and if H200 is capable of training why not use the same GPU for inference as well?
Let’s get to it.
Quick answer for impatient readers: xD
The main difference between the NVIDIA H200 and NVIDIA L4 is what type of AI workload each GPU is designed to handle efficiently.
Think of it this way:
-
NVIDIA H200 GPU: A powerful industrial machine designed to handle extremely demanding AI calculations, large models, and heavy training workloads.
-
NVIDIA L4 GPU: A compact, energy-efficient machine designed to run AI applications, process requests, and perform inference without consuming excessive power.
Both are NVIDIA data-center GPUs, but they serve different purposes.
First, understand AI training vs AI inference
Before comparing the GPUs, you need to understand two important concepts.
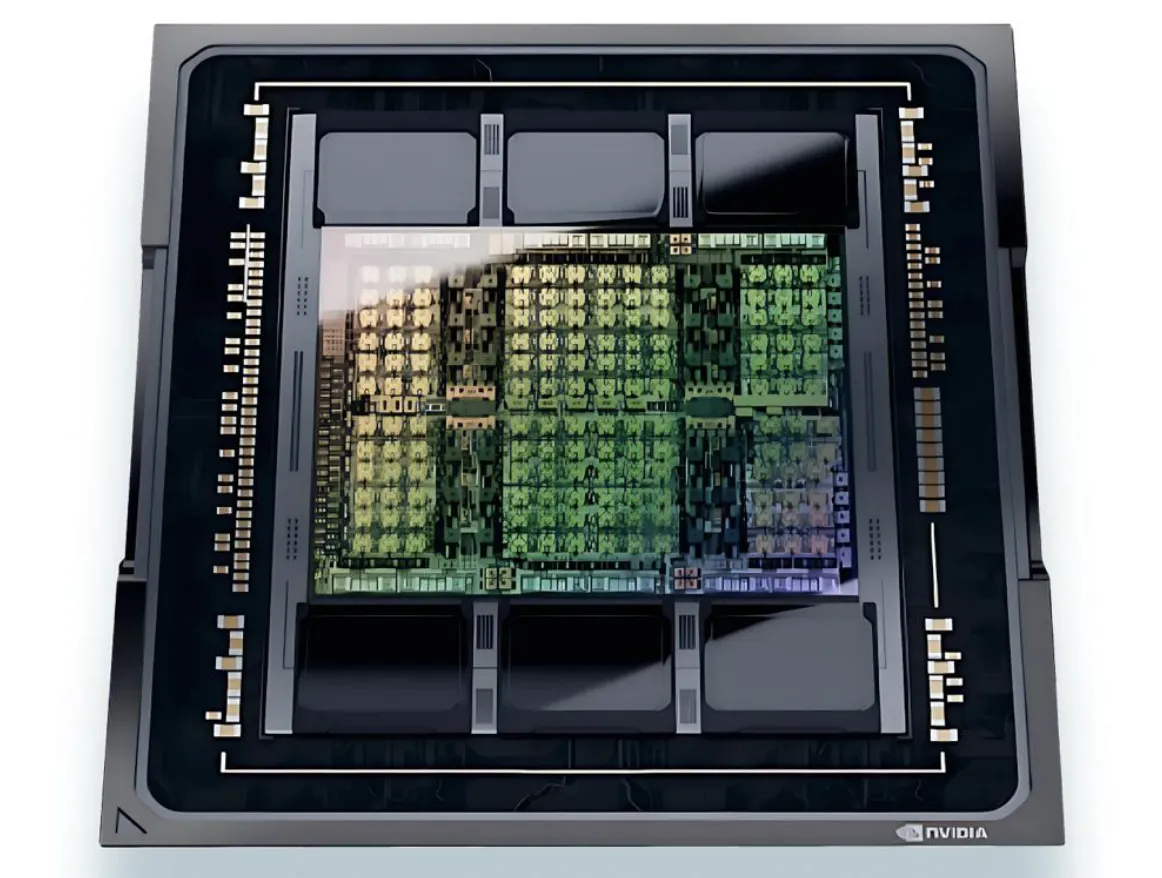
NVIDIA H200 Tensor Core GPU — The training giant
Imagine teaching an AI model to understand millions of documents, images, and conversations. Training involves enormous mathematical calculations, large amounts of GPU memory, and repeated updates to the model.
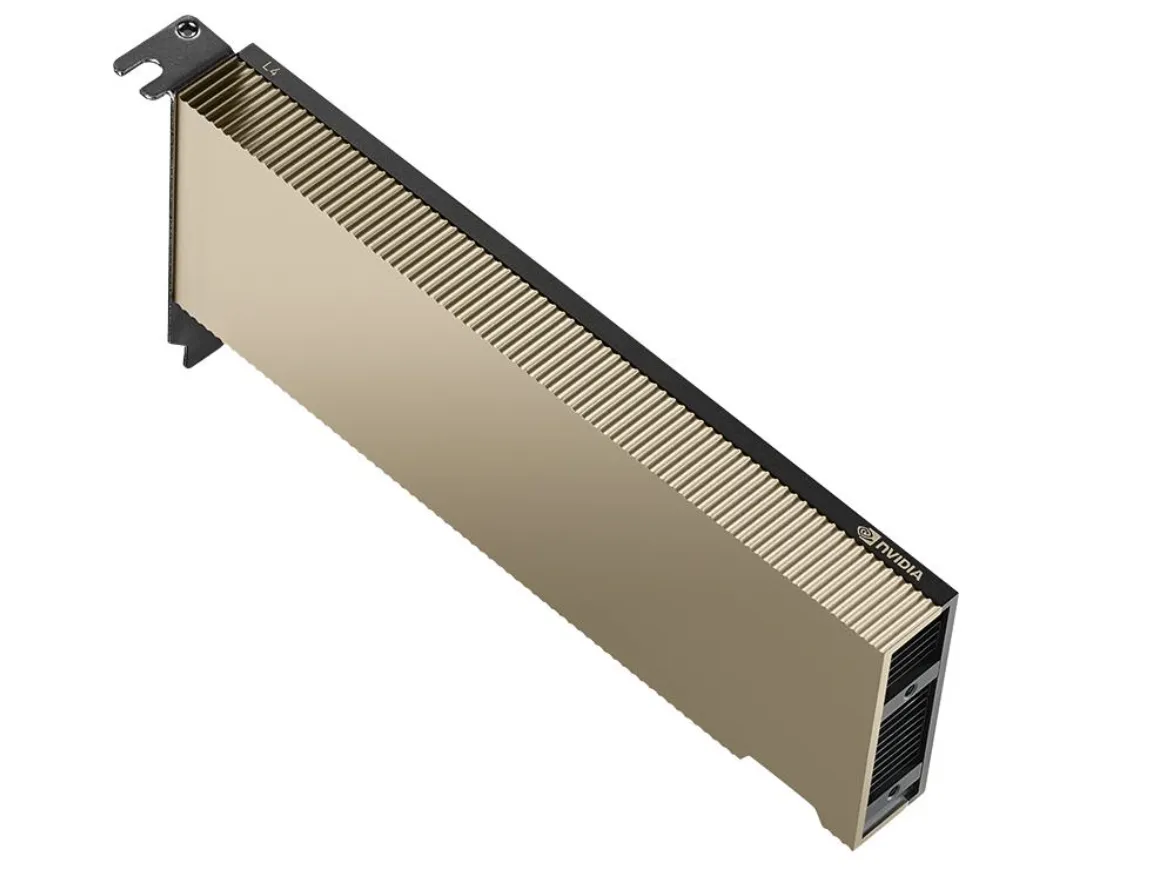
NVIDIA L4 Tensor Core GPU — The inference saver
Imagine an AI model has already been trained. Now thousands of customers want to ask questions, generate content, or analyze images. Inference is the process of using that trained model to produce answers.
A simple example
Suppose you’re developing an AI chatbot for a company.
Stage 1
Training: You train or fine-tune the chatbot using company documents, support conversations, and technical knowledge. A GPU like the H200 can be useful for demanding training workloads.
Stage 2
Inference: After the chatbot is ready, customers start asking questions. The GPU processes those requests and generates answers. An L4 can be a cost-effective choice if the model fits its memory and meets performance requirements.
The important point is that training and inference have different hardware requirements.
H200 vs L4: Technical specifications
Here are the official NVIDIA specifications. For the H200, we’re comparing the SXM version.
|
Specification |
NVIDIA H200 SXM |
NVIDIA L4 |
|
Architecture |
Hopper |
Ada Lovelace |
|
GPU memory |
141 GB HBM3e |
24 GB GDDR6 |
|
Memory bandwidth |
4,800 GB/s |
300 GB/s |
|
Maximum TDP |
700 W |
72 W |
|
FP32 performance |
67 TFLOPS |
30.3 TFLOPS |
|
PCIe interface |
PCIe Gen5 |
PCIe Gen4 |
|
NVLink |
Supported |
Not supported |
|
Primary strengths |
Large AI models, training, large-scale inference, HPC |
Efficient inference, video processing, graphics |
|
Physical design |
SXM module |
Low-profile PCIe card |
Three differences are especially important.
-
GPU memory
-
Memory bandwidth
-
Power consumption
GPU memory: Why 141 GB vs 24 GB matters
Think of GPU memory (VRAM) as the working space available to an AI model.
A model needs memory for its parameters, temporary calculations, and input/output data.
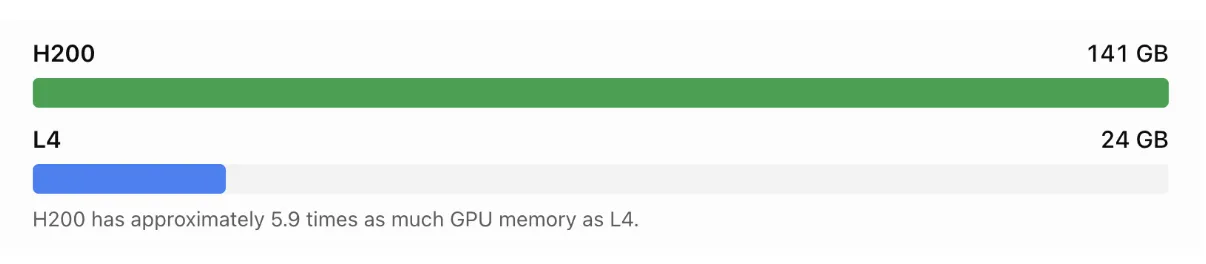
GPU memory capacity
Example: Running a 70-billion-parameter AI model
Suppose you want to run a 70B model using FP16 precision.
Each parameter typically requires 2 bytes.
That is approximately 140 GB just for the model weights.
-
L4: Its 24 GB memory cannot hold the full model in FP16 on a single GPU.
-
H200: Its 141 GB memory is approximately equal to the weight requirement, but there is not enough practical headroom for runtime overhead and KV cache.
With quantization, memory requirements can decrease significantly, potentially making a 70B model practical on a single H200. Smaller quantized models may fit on an L4.
⭐Key lesson: GPU memory determines which models you can realistically run, not just how fast they run.
Memory bandwidth: Why H200 handles large models better
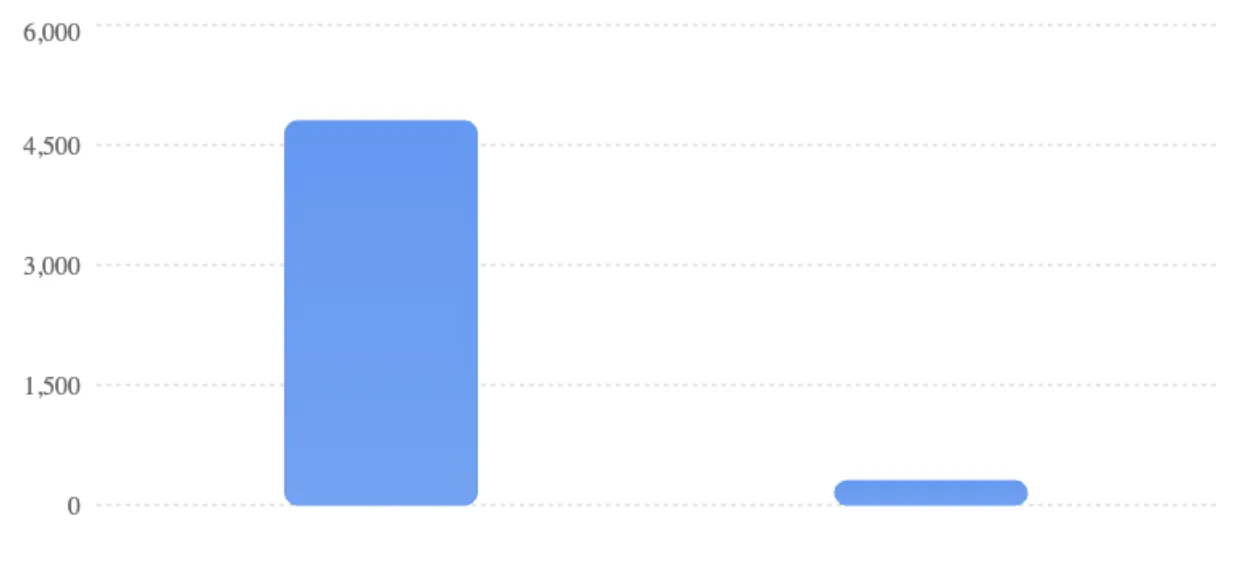
Memory bandwidth measures how quickly the GPU can move information between its memory and processing units.
Imagine two warehouses:
-
Warehouse H200 can move 4,800 boxes per second.
-
Warehouse L4 can move 300 boxes per second.
The H200 can move 16 times as much data per second.
GPU memory bandwidth
Theoretical peak memory bandwidth, GB/s
Why is this important?
Large language models frequently need to read enormous amounts of model data during inference.
If memory cannot deliver data fast enough, the GPU’s computing units may spend time waiting.
The H200’s higher bandwidth can significantly improve performance for memory-bandwidth-intensive AI workloads.
However, 16 times the memory bandwidth does not automatically mean 16 times faster inference. Actual performance also depends on model size, batch size, precision, and software optimization.
Power consumption: Why L4 can save money
Now consider operating costs.
The H200 SXM has a maximum configurable TDP of up to 700 W.
The L4 has a maximum TDP of 72 W.
Suppose both GPUs operated at their maximum rated power continuously for 30 days.
Illustrative GPU-only estimate based on maximum TDP, not measured consumption. Excludes CPU, RAM, cooling, networking, power supply losses, and other server costs.
The L4’s much lower power requirement makes it attractive for organizations deploying many inference servers.
But there is an important consideration.
If an H200 can process significantly more inference requests per second, its cost per completed request could still be competitive or even lower.
So comparing electricity consumption alone is not enough.
Which GPU should a customer choose?
Dropping some practical examples so you understand even better.
Imagine three different customers approaching a GPU hosting provider.
Customer A: AI research company
They want to fine-tune a large language model using billions of tokens.
→ Better fit: H200. Large memory, high bandwidth, and powerful tensor compute make it suitable for demanding training and fine-tuning.
Customer B: SaaS chatbot company
They want to run a quantized 7B or 8B chatbot model for customer support.
→ Potentially better fit: L4. Its 24 GB memory can support many smaller quantized models, while its low power consumption helps control operating costs.
Customer C: Video streaming company
They need AI-powered video processing, encoding, and analytics.
→ Better fit: L4. It has dedicated video engines, including AV1 encode/decode capabilities, and is designed for efficient video and AI workloads.
NVIDIA specifically positions the L4 for efficient AI, video, and graphics acceleration.
7. Important: H200 is not only for training
The title Training Giant or Inference Saver? is a useful way to remember their strengths, but it is not a strict technical distinction.
The H200 is also an extremely capable inference GPU.
For example, a company serving a large 70B language model to many simultaneous users might benefit from H200 memory capacity and bandwidth.
Similarly, the L4 can handle smaller AI training and fine-tuning workloads.
The choice depends on the workload, not simply whether it is called training or inference.
8. How should a GPU hosting provider recommend these GPUs?
When a customer asks for an H200 or L4 GPU server, first understand the workload.
|
Customer requirement |
Likely starting choice |
|
Training large AI models |
H200 |
|
Fine-tuning large LLMs |
H200 |
|
Running smaller quantized chatbots |
L4 |
|
Serving large LLMs with high throughput |
H200 |
|
Video encoding and AI video analytics |
L4 |
|
Energy-efficient edge inference |
L4 |
|
Scientific computing and HPC |
H200 |
|
Small-scale model experimentation |
L4, if memory is sufficient |
For a real deployment, ask the customer about model size, precision, expected concurrent users, latency requirements, GPU memory needs, and monthly budget.
For inference, compare:
-
Tokens per second: How much text the system generates.
-
Time to first token: How quickly the first response begins.
-
Concurrent requests: How many users can be served simultaneously.
-
GPU utilization: Whether the hardware is being used efficiently.
-
Cost per million tokens: How much useful inference output costs.
For training, compare time per step, total training time, GPU memory, communication overhead, and cost per completed training run.
Final verdict
NVIDIA H200 GPU
Best suited to demanding AI training, large-model inference, and HPC workloads where high memory capacity and bandwidth are critical.
NVIDIA L4 GPU
Best suited to smaller-model inference, AI video processing, and power-efficient deployments where the workload fits within 24 GB.
The most important takeaway is:
H200 is built for handling demanding AI workloads at scale. L4 is built for delivering useful AI acceleration efficiently.
A customer running a small chatbot does not necessarily need an H200. A customer training a massive AI model should not expect an L4 to deliver comparable performance.
For cloud and GPU hosting businesses, the goal is to recommend the GPU that delivers the required performance at the lowest practical total cost—not simply the GPU with the highest specifications.